Clustering-Based Lightweight Architecture for Image Captioning
Abstract
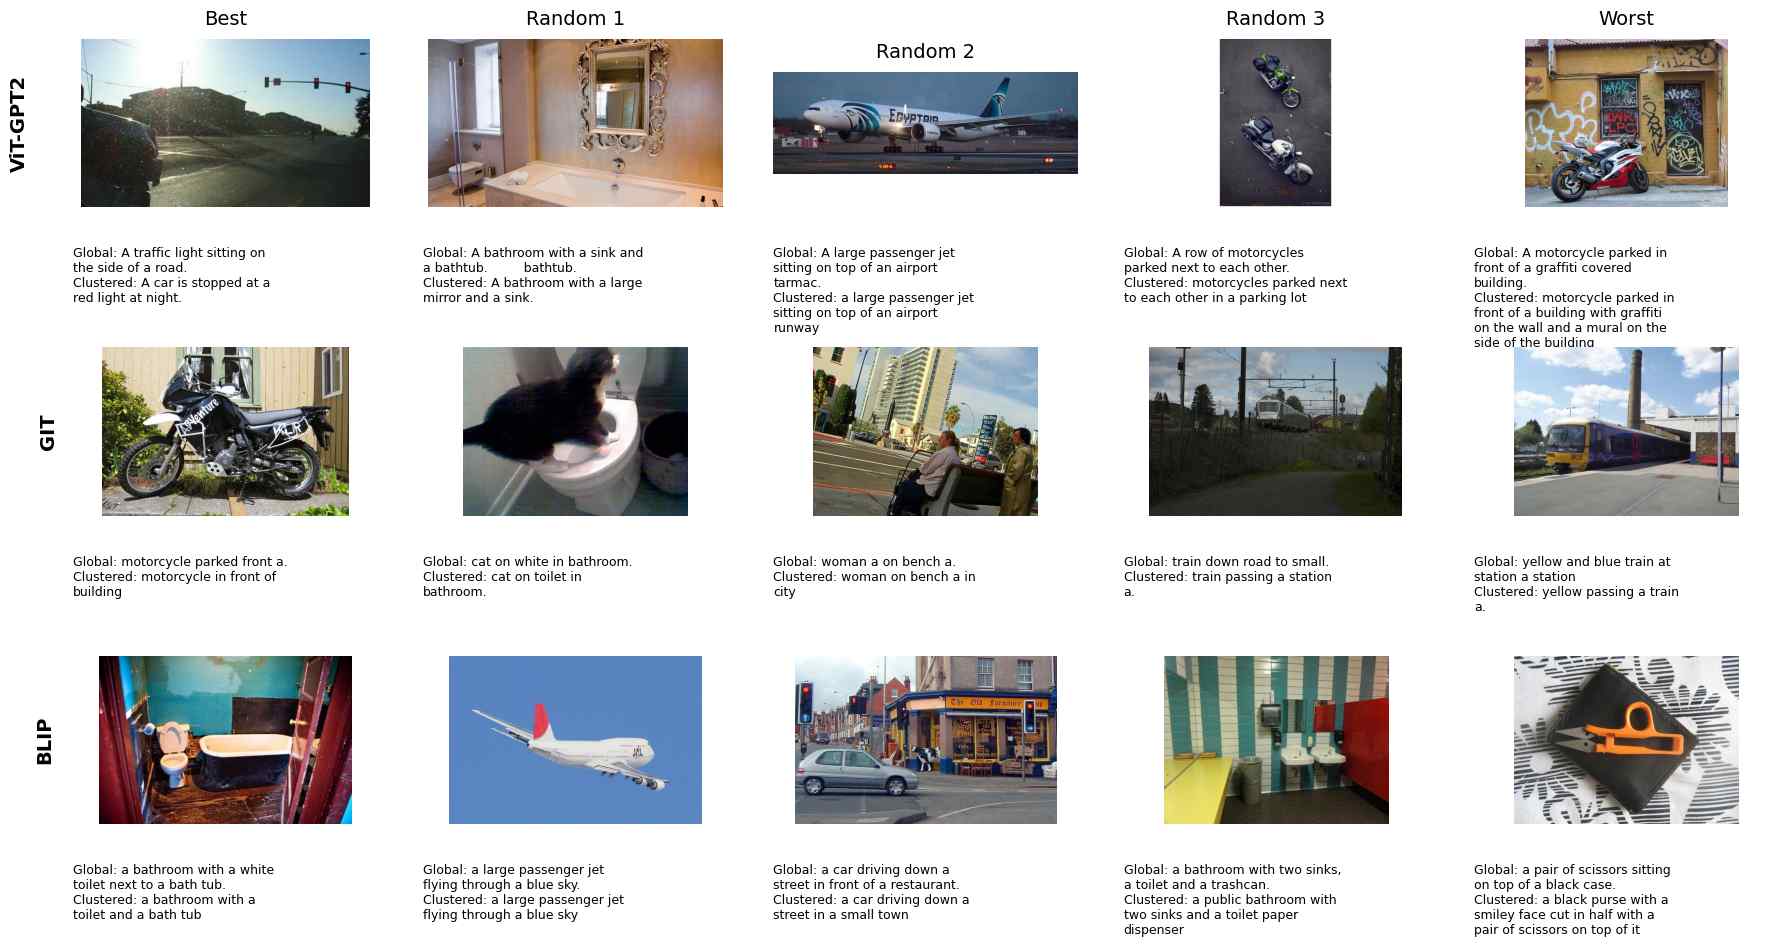
Recent advances in vision–language models have significantly improved image captioning performance; however, existing systems often produce generic or semantically shallow descriptions, particularly when trained on large and non-uniform datasets. In this work, we propose a clustering-based framework for image captioning that organizes image–caption pairs into semantically coherent groups prior to model training. We then train a cluster-conditioned caption generation model that leverages cluster identity as additional contextual information, enabling more specialized and context-aware caption generation. We evaluate our approach on the Microsoft COCO dataset with BLEU, ROUGE-L, and METEOR across three models: ViT-GPT2, GIT, and BLIP. The results show that clustering does not consistently improve overall performance compared to training on the full dataset, with mixed results depending on the model and metric. However, when we look more closely at individual examples, we find that clustering can help generate more specific and relevant captions in certain cases.
Results