Sketch-Guided Diffusion for Image-to-Image Generation
Abstract
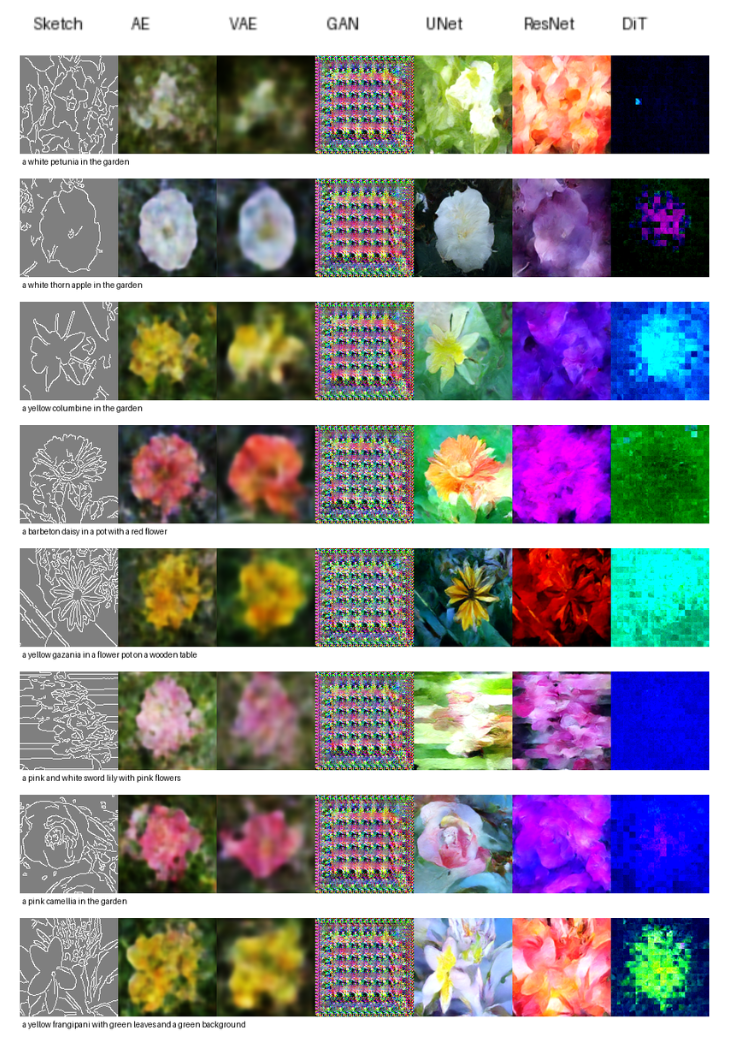
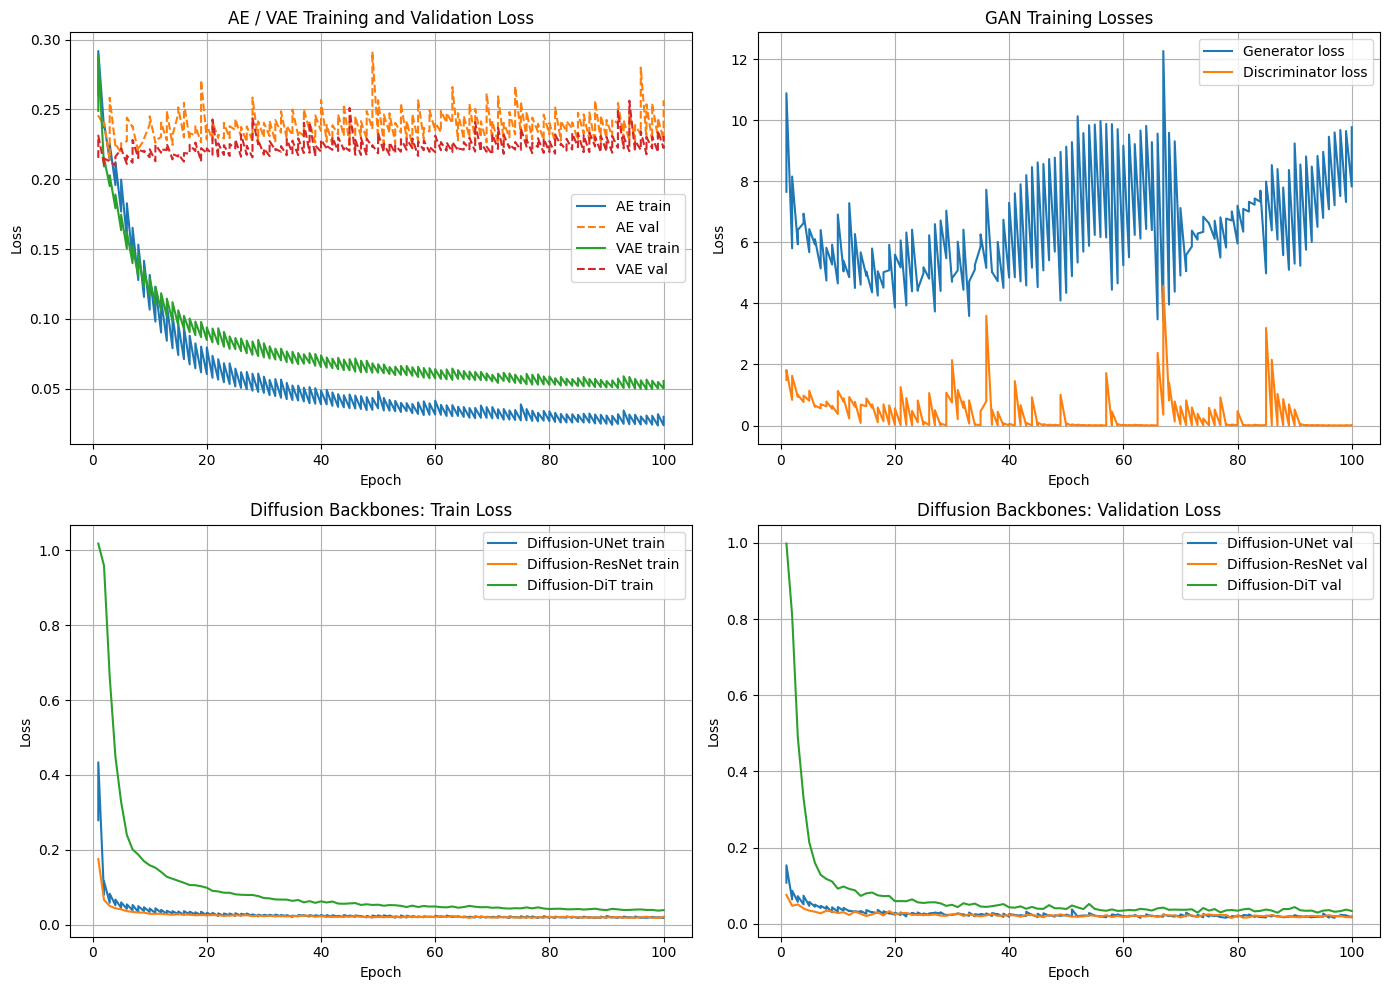
This work investigates diffusion-based image generation from sketch and text inputs. Using the DDPM framework, the denoising process is conditioned on a Canny-edge sketch, a CLIP text embedding, and the diffusion timestep. Three backbone architectures—U-Net, ResNet, and DiT—are trained under identical settings to isolate architectural differences. Due to computational constraints, training is performed at a small resolution and for a limited number of epochs. As a result, the outputs are preliminary but still informative. Qualitative results indicate that AE and VAE models tend to produce blurred images, while diffusion-based approaches preserve more structural detail from the sketch and capture richer color variations from the caption. These early findings suggest the potential of sketch- and text-guided diffusion models for producing images with more artist-like structure and interpretability.
Results